Ship faster, break less, sleep better
The automation and safeguards that get your software live quickly, reliably, and safely, and keep it healthy once it's there. Set up in your accounts, documented, and run by your people.
- 01 CI/CD Fast, low-risk releases
- 02 Infra as code Consistent, repeatable setup
- 03 Monitoring Know before customers do
When shipping is scary, everything slows down
Engineers stuck firefighting aren't building, and fragile deployments are the reason AI never quite makes it to production.
-
Slow, manual deploys
Shipping takes hours of careful manual steps, so releases are rare, dreaded, and easy to get wrong.
-
Things break in production
Something works locally, then falls over live, because environments drift and nothing catches it first.
-
No visibility
When something goes wrong, you find out from an angry customer, not a dashboard or an alert.
-
Always firefighting
Your engineers spend more time keeping the lights on than building, and burnout creeps in.
The pieces that make shipping safe
Shipping that's fast and boring
Automated pipelines that build, test, and release code on every merge, so shipping stops being a scary event and becomes a routine one. Rollbacks are one click, and a bad deploy never reaches every user at once.
- Automated tests
- One-click deploy
- Safe rollbacks
- Staged releases
Servers defined in code
Infrastructure written as code so every environment is consistent, repeatable, and version-controlled. Spin up a matching staging environment in minutes and rebuild production exactly if you ever have to.
- Reproducible
- Version-controlled
- No drift
- Fast recovery
Know before your customers do
Dashboards and alerts that surface problems the moment they start, wired to the metrics that matter, latency, errors, saturation, and spend, so you hear it from a system, not an angry customer.
- Live dashboards
- Smart alerts
- On-call runbooks
- Fewer surprises
Systems that hold under load
Setups that stay up under pressure and scale with demand, auto-scaling, health checks, and load-tested limits, so a record traffic day for the business isn't a bad day for the servers.
- High uptime
- Auto-scaling
- Load-tested
- Zero-downtime deploys
What working with us looks like
What's included
-
01
CI/CD pipelines
Automated pipelines that build, test, and release code safely on every change, so shipping is fast and low-risk.
- Build & test on merge
- One-click deploy
- Automatic rollbacks
-
02
Infrastructure as code
Servers and environments defined in code, so they're consistent, repeatable, and easy to recover or clone.
- Terraform / IaC
- Repeatable environments
- No config drift
-
03
Monitoring & alerting
Dashboards and alerts that tell you about problems before your customers ever notice them.
- Metrics & logs
- Smart alerts
- On-call runbooks
-
04
Reliability & scaling
Systems set up to stay up under load and scale smoothly as demand grows, tested against real spikes.
- Auto-scaling
- Health checks
- Load-tested
-
05
Security & secrets
Access controls, secrets management, and safe defaults baked into the pipeline from the start.
- Managed secrets
- Least-privilege access
- Scans in CI
-
06
Handover & documentation
Runbooks, docs, and training so your people can run and extend everything once we hand it over.
- Runbooks
- Training
- You own it all
Assess, automate, hand it over
We assess the current setup, put the automation and safeguards in place, and hand it over documented, so your people can run it without us.
Book a discovery session-
01 / 05
Assess the current setup
We review how you build, ship, and monitor today, and pinpoint what's slow, manual, or risky.
-
02 / 05
Plan the pipeline
A clear plan for CI/CD, infrastructure, and monitoring that fits your stack, agreed before we build.
-
03 / 05
Put automation in place
We build the pipelines, infrastructure-as-code, and safeguards, working alongside your existing tools.
-
04 / 05
Add monitoring & alerts
Dashboards and alerting so problems surface early, with clear runbooks for when they do.
-
05 / 05
Hand over, documented
We document everything and train your people, so you own it and can run it without us.
Two ways in. One team behind both.
Most companies are in one of two places. Pick yours — we'll meet you there.
-
Firefighting
“Every release is scary and something always breaks in production.”
Manual deploys, no monitoring, and people stuck putting out fires instead of building. We assess the setup and put automation and safeguards in place so shipping stops being an event.
Book a discovery session -
Ready to Level Up
“We know what we need. We just need it set up properly.”
You know CI/CD and monitoring would help, you just need it built right and handed over. We set it up in your accounts, documented, so your people can run it.
Book a discovery session
Ops people who've kept real systems running
Senior practitioners, not a rotating bench of junior hires. We've owned production pipelines and on-call, and we set everything up so your team can run it without us.
Reliability is the product
The whole point here is uptime. We build safeguards and monitoring so what you ship keeps running.
Set up in your accounts
Pipelines and infrastructure live under your logins, documented, so your people can run it. No lock-in, ever.
Honest about what you need
If part of this is overkill for your size, we'll tell you. We set up what earns its keep, nothing more.
Senior team, fixed price
Senior practitioners who've run production systems, on a fixed price for fixed scope, never hourly.
Reliable ops is what lets AI actually run in production
We say it everywhere: production, not demos. The thing that gets an AI system from a slick demo to something you can depend on is exactly this, solid pipelines, monitoring, and infrastructure that hold up.
Models drift, traffic spikes, and prompts change, so we treat AI like any other production workload: versioned deploys, automated evals in the pipeline, GPU-aware autoscaling, cost guardrails, and alerting on quality, latency, and spend, not just uptime.
- Production, not a demo
- You own the code, the prompts and the accounts
- Fixed price on the scope we agree
- Repeatable deploys Ship AI updates without fear
- Live monitoring Catch drift and failures early
- Automated evals Quality checked before release
- AI that stays up Demos become dependable systems
- We walk the work with you Thirty minutes on how the job actually moves today, step by step, in your vocabulary rather than ours.
- We mark where AI pays and where it does not Two or three places it would earn its keep, the places it would not, and a rough number against each.
- You keep the map either way Written up and sent over, yours to build with us, build elsewhere, or shelve. No follow-up sequence.
And if AI is the wrong tool for a step, we will say so on the call. Plenty of the work below is better done with plain software.
Frequently asked questions
The things companies ask us before the first working session. Still curious? Just ask.
We're a small company, isn't this overkill?
Usually the opposite. Small companies gain the most, because automation and monitoring save the exact hours a small team can't spare. We right-size it to your scale, so you get the safety without the enterprise overhead.
Will you work with our existing setup?
Yes. We build on the cloud, tools, and workflows you already use wherever we can, rather than forcing a rip-and-replace. We'll only suggest a change when the current setup is actively costing you.
Do we need to switch tools?
Rarely. We work with mainstream CI/CD, cloud, and monitoring tools, so in most cases we improve what you have. If something genuinely won't hold up, we'll explain why before changing it.
Can our engineers run it after you leave?
Yes, that's the goal. Everything is set up in your accounts and documented with runbooks, and we train your people, so you're never dependent on us to ship or recover.
How does this help us run AI?
Reliable pipelines, monitoring, and infrastructure are exactly what AI systems need to run safely in production. Good DevOps is what turns an AI demo into something dependable.
Work we’ve built and handed over
Every figure below is real and shared with the customer's permission. Three of the five asked not to be named, so we describe them by niche instead.
-
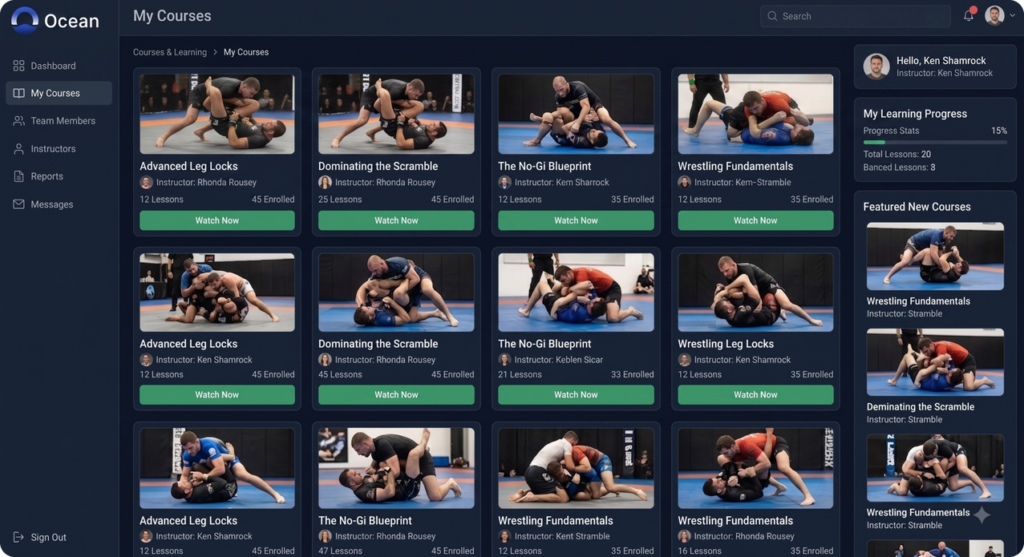 Sports E-learning
Athletes Ocean: one platform where athletes teach and coaches buy for their teams
2,036% Net sales growth YoY 0.7s Page load, from 16.7s View case study -
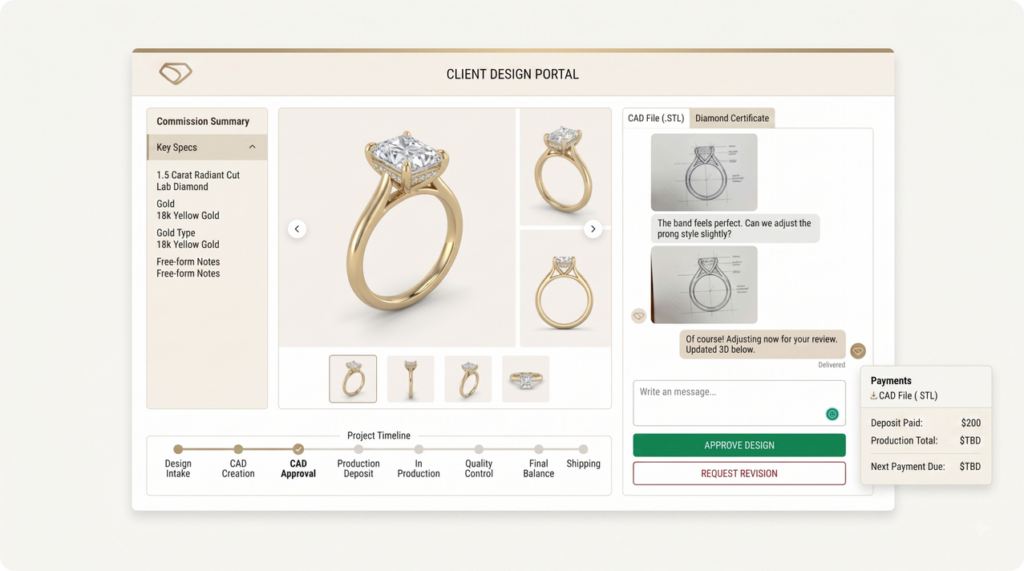 Jewelry
A WooCommerce store turned into a custom-ring design studio
10 Production stages on rails 2-way GoHighLevel sync View case study -
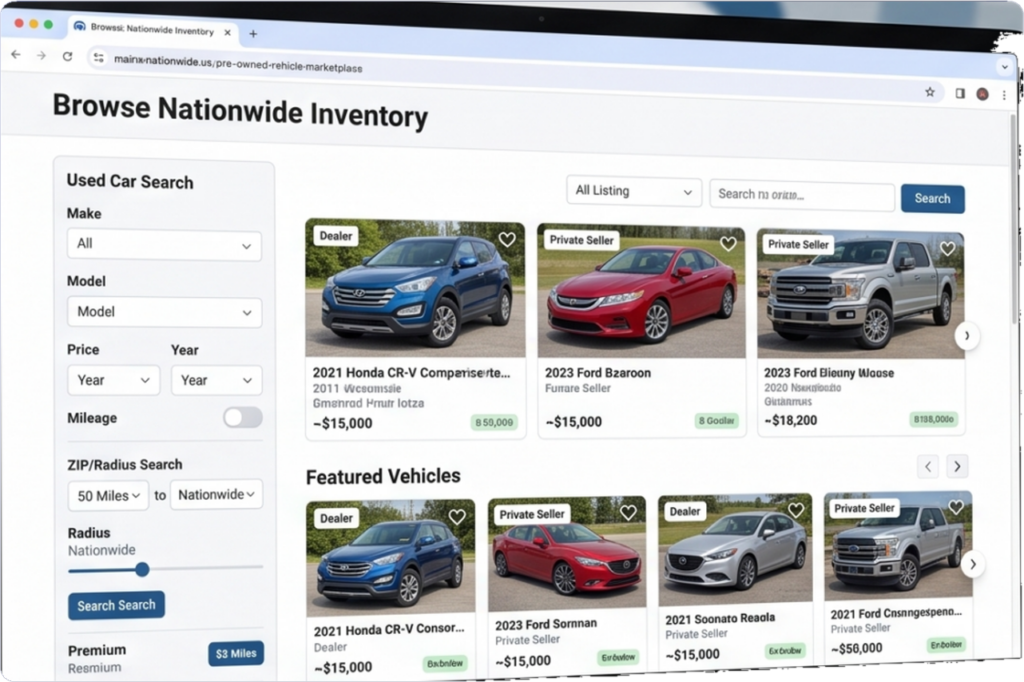 Automotive
A nationwide pre-owned vehicle marketplace
2 Seller models, one platform 50mi+ Radius search to nationwide View case study